Filtering AI Code Review Comments with Jev
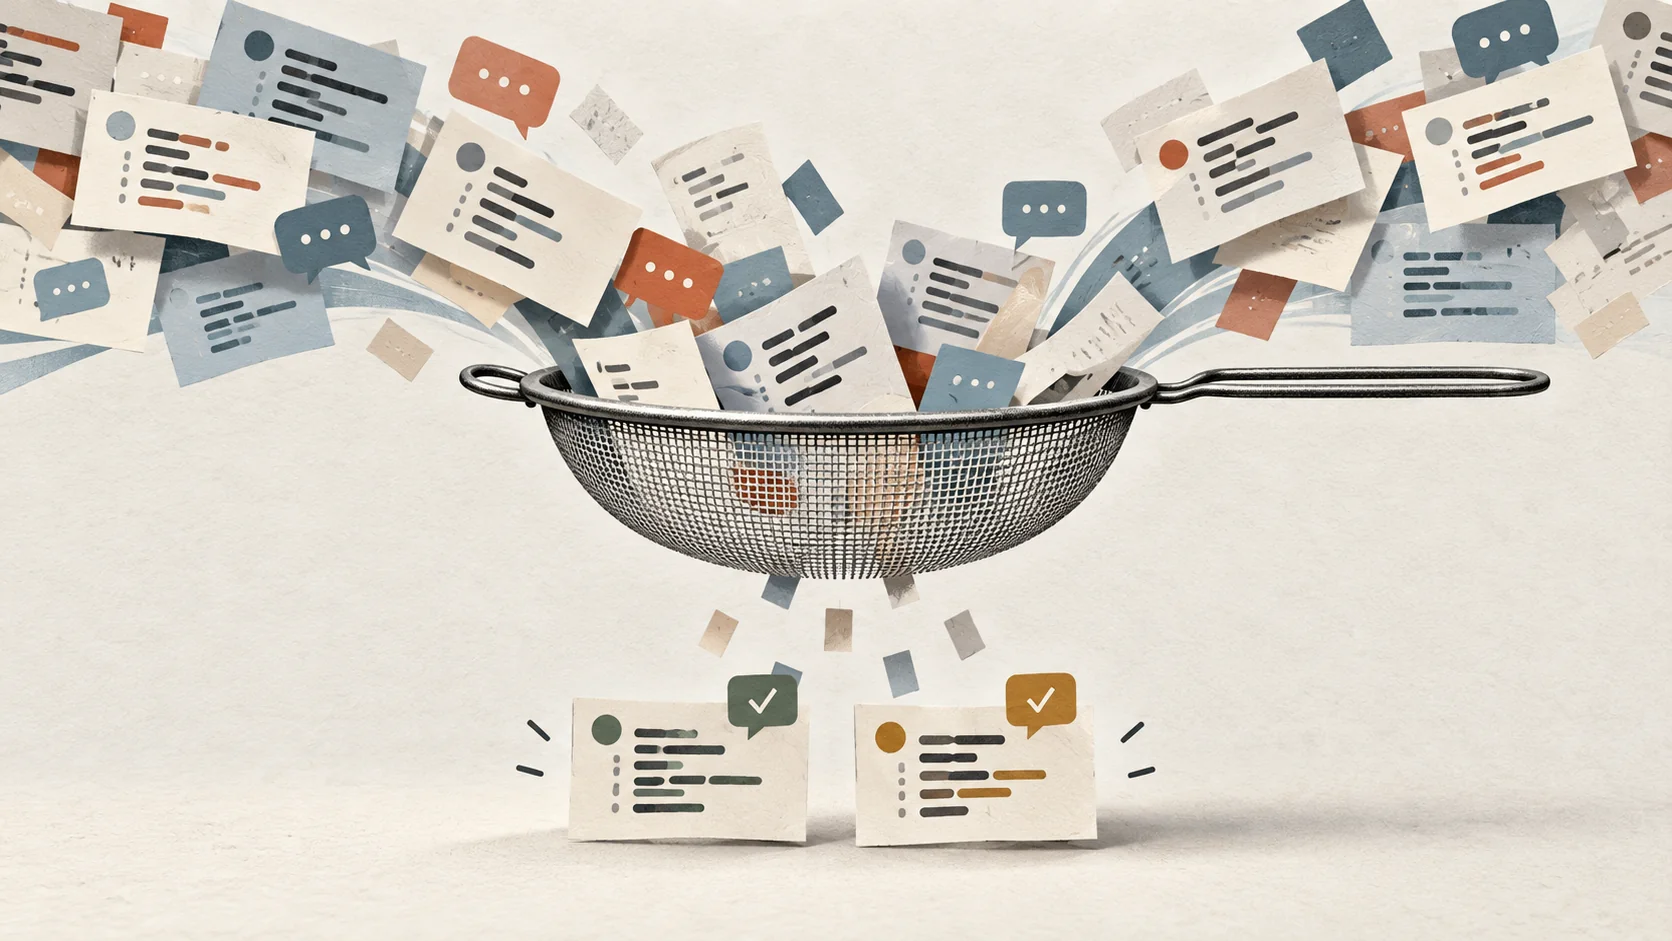
When I ask an AI agent to review a pull request, I usually get back a second review to do. There’s a list of possible bugs, and I still have to figure out which ones are real, whether the consequences actually follow, and which are worth bothering the author about.
The agent sounds equally sure about all of them. The division-by-zero warning might have missed an early return three lines up. The maintainability suggestion might be fine but not something I’d hold a merge over. Meanwhile the one serious bug is sitting in the middle of the list looking like everything else.
So I built a skill called jev-review-triage to do that sorting for me. The coding agent proposes findings, Jev answers a handful of narrow questions about each one, and a Python script decides what survives and in what order. The agent writes the final review from whatever is left.
I’ll walk through it with two small examples. The scores later in the post are made up to show how the policy works. I haven’t measured whether this produces better reviews.
What Jev is
Jev is pretty new, so a quick primer first.
Jev is a model from TypeSafe, and it’s the first of what they call System One models. The name echoes Kahneman’s “System 1,” the fast, intuitive kind of thinking, as opposed to slow, deliberate reasoning. A System One model doesn’t write text. You give it some state (a JSON blob of whatever it needs to look at) and one or more questions, and it gives back typed answers with probabilities attached.
You don’t ask Jev open-ended questions like “what’s wrong with this code?” You define the possible answers up front with one of three primitives:
- Noul answers a yes/no question and returns the probability that the answer is yes.
- Choice picks one option from a list you provide and returns a probability for each option.
- Score places something on an ordered scale you describe, like “cosmetic” through “data loss”, and returns a probability for each level.
A single request can mix all three. Each question is evaluated on its own, in parallel, so one question’s answer can’t leak into another’s, and according to the docs, adding questions barely changes the response time.
Jev can’t explain itself, write code, or reason through a multi-step problem. That’s a job for a general-purpose LLM. What it does is make one narrow judgment quickly and return an answer your code can use without parsing.
Why use it here
My coding agent is already an LLM. Why not have it check its own findings?
You can, but the answers aren’t something I can build on. If I ask the agent “is this finding real?”, I get a paragraph back. Sometimes it’s “yes,” sometimes “likely,” sometimes “this could be an issue depending on…”. I can’t set a threshold on “likely.” Worse, the agent that just talked itself into a finding is the one grading it.
Jev addresses a few of those problems:
- The answers are typed. A Noul comes back as a number between 0 and 1. My script can compare it to
0.35without regexes or asking the model to “respond only in JSON.” - I get probabilities, not just verdicts. A 0.5 on “is this claim true?” is useful. It tells me to send the finding back for a closer look instead of forcing a yes or no.
- Questions stay separate. I can ask whether the claim is true and how severe it would be in the same request, and a scary-sounding severity can’t talk the model into believing the claim. Each answer is its own judgment.
- Policy lives in code. Jev supplies the judgments, and Python decides what they mean. If I want fewer nitpicks, I change a number in a file and don’t have to rewrite a prompt. Given the same scores, the script always produces the same verdict.
- It’s a second opinion from a different kind of model. The model that proposed the finding doesn’t get to approve it.
If you’ve ever written “prompt the LLM, parse the output, hope the format holds” for a classification or yes/no step, that’s where Jev fits. This review filter is one example of that pattern.
Who does what
A skill is just a set of instructions (plus some supporting scripts) that an agent follows for a particular task. Mine tells the agent how to pull the PR’s code, write up candidate findings, run the scoring script, and put together the report.
The agent still does the actual reviewing: reading the diff, poking around the surrounding code, thinking up ways things could break. Jev gets a much smaller job. It’s handed one claim and some evidence and asked whether the claim holds up.
This skill only uses two of the primitives: Noul for the yes/no checks and Score for severity.
flowchart TD
    A["Coding agent proposes findings"] --> B["Jev evaluates each finding"]
    B --> C["Python applies the review policy"]
    C --> D["Keep comments and minor notes"]
    C --> E["Uncertain: agent inspects more code"]
    C --> F["Drop or mark duplicate"]
    E --> G["Confirm or reject the finding"]
    D --> H["Agent writes the sorted review"]
    G --> H
I tell the agent to be generous when generating candidates, marginal ones included. The filter can only throw things away, so anything the agent doesn’t write down is gone for good. That costs more Jev calls, and it doesn’t mean the filter will catch every bad suggestion, but I’d rather check too much than too little.
The raw candidate list never shows up in the report. If it did, the reader would have to wade through the noise the skill exists to remove.
Making a finding checkable
Each candidate has to include a factual claim, a concrete failure scenario, the diff hunk, and enough surrounding code from the PR’s head revision to judge it. It also carries the file and line and any repo conventions that matter.
Here’s a simplified cache. The dictionary is shared across all stores, and build computes a store’s order totals for a product category:
def get_or_build(cache, store_id, category, build):
    key = f"summary:{category}"
    if key in cache:
        return cache[key]

    value = build(store_id, category)
    cache[key] = value
    return value
Say the PR adds this function. “Caching looks risky” is useless as a finding. Something like this gives Jev an actual claim to test:
{
  "claim": "The cache key omits store_id, so different stores share a cached summary.",
  "failure_scenario": "Store A requests shoes and caches a total of 12 orders under summary:shoes. Store B, which has 3 shoe orders, requests shoes and gets A's cached total of 12."
}
That’s only part of the candidate. The agent also sends the patch and the function itself.
You can trace this one by hand. The first call writes to summary:shoes, and the second call returns that value before it ever gets to build. store_id only matters on a cache miss.
Here’s the second candidate:
def average_rating(reviews):
    if not reviews:
        return 0.0
    return sum(r.stars for r in reviews) / len(reviews)
The claim: “average_rating divides by the list length without checking for an empty list.” The failure scenario: an empty list raises ZeroDivisionError.
The function is real and so is the division. The claim is still wrong, because the guard is right there, and the empty-list case never reaches the division. That’s why “does this code exist?” can only be the first question.
Six questions per finding
For each finding, the script sends all of these at once:
| Question | What it checks |
|---|---|
| Grounding | Does the described code element exist in the supplied code? |
| Claim | Is the claim a true description of that code? |
| Failure | Does the proposed failure scenario follow from the code? |
| Novelty | Did the PR introduce the problem? |
| Severity | Assuming the defect is real, how serious is its consequence? |
| Worth | Does it justify asking for a change before merging? |
This is the claim question from the script, using the Python SDK:
"claim": Noul(
    instructions=(
        "Reading `diff_hunk` together with `file_context`, is the statement in "
        "`finding.claim` a true description of this code as written?"
    ),
    criteria=NoulCriteria(
        true="the code is as `finding.claim` describes it",
        false="the code is not as `finding.claim` describes it; the statement "
        "misreads the supplied code",
    ),
),
It’s one entry in a dictionary of questions, with Noul and NoulCriteria imported from typesafe_sdk. Every question gets its own answer, which matters because findings fail in different ways. One might describe the code correctly and get the consequence wrong. Another might point at a real problem that still isn’t worth blocking on.
Five of the questions come back as 0–1 probabilities. Severity uses a 0–4 rubric that I wrote for this skill: style, maintainability, visible failure under unusual conditions, visible failure in normal use, and at the top, silent wrong results, data corruption, or a security hole in production. It isn’t meant to line up with anyone’s P0–P3 labels.
The severity score is the probability-weighted average across those levels, and the label shown is whichever level is most likely. Severity confidence tells you how spread out that distribution is. It says nothing about whether the bug exists. TypeSafe’s confidence docs go into the difference.
Python makes the call
The thresholds are plain Python. With the current defaults, a grounding or claim score below 0.35 drops the finding. If both clear 0.35 but either is under 0.70, the finding is marked ESCALATE and the agent goes and looks more closely.
The failure question uses the same cutoffs: under 0.35 is a drop, 0.35 to just under 0.70 is an escalation, and 0.70 and up passes. After that, a worth score under 0.55 turns the finding into a minor note. Anything above is a comment candidate.
Pure style or maintainability findings can set asserts_failure=false, and the policy skips the failure check for them. Anything that claims wrong output, a crash, or some other runtime effect has to pass it, however severe it looks.
Suppose our two examples came back with these made-up scores:
| Judgment | Store cache | Guarded division |
|---|---|---|
| Grounding | 0.98 | 0.98 |
| Claim | 0.97 | 0.04 |
| Failure | 0.96 | 0.05 |
| Novelty | 0.95 | 0.20 |
| Worth | 0.96 | 0.10 |
| Severity, out of 4 | 4.00 | 2.90 |
| Verdict | COMMENT | DROP |
The division finding gets dropped even with a 2.9 severity. Severity is scored as if the bug were real, so it can’t rescue a claim that failed. The cache finding passes, and the agent drafts something like:
Could we include
store_idin the cache key? Right now two stores asking for the same category share an entry, so the second store gets the first store’s totals. It’d be good to add a test that makes both requests and expects different totals.
COMMENT just means the report includes a suggested comment. Nothing gets posted to GitHub. NOTE is a one-line minor observation. For ESCALATE, the agent reads more code and either confirms or rejects the finding. If it confirms one, the report keeps Jev’s original scores.
There’s optional SonarQube deduplication too. Python picks out nearby issues in the same file and asks Jev whether each describes the same defect. A score of 0.70 or higher marks the finding DUPLICATE. That check runs after grounding and claim but before the failure check. If SonarQube isn’t set up, the report says so.
A novelty score under 0.40 flags the issue as possibly pre-existing, so the agent compares against the base revision. It doesn’t drop anything by itself. Whatever survives is sorted by severity, highest first, with claim score as the tiebreaker. All the prose is the agent’s.
Where it can go wrong
Jev only knows what it’s sent. Leave out a guard clause or a helper function and you can get a different answer. I try to send the surrounding function and whatever it depends on, enough to settle the claim. Pasting the whole module into every request mostly adds noise and can still miss the one fact that mattered.
When this workflow calls a finding “verified,” it means the model thought the failure scenario followed from the code. Nothing was run and nothing was proven. Getting a typed answer back makes it easy for code to act on. It can still be wrong.
I also haven’t tuned the defaults for any particular repo. To tune them properly, I need to read what got rejected as well as what got through. When a real bug gets dropped, I check the evidence that was sent first, then the question wording, then the threshold. A short report is nice, but I still want a way to see what the filter threw away.
The skill’s offline tests mock the model responses and check the decision boundaries. They tell me nothing about how accurate Jev is. I don’t have precision or recall numbers. The script also calls jev-latest, so the judgments can shift under me. The Python side is deterministic, since the same scores always produce the same verdict, but there’s no promise the model will return the same scores next week.
What I’ve actually got is a place where the review policy is written down and easy to change. Too many nitpicks getting through? Look at the worth scores. Real bugs disappearing? Look at the claims, the context, and the cutoffs. I’d want to do a lot more of that before I’d say the shorter report is actually a better review.